Nobody has time to read the whole database
A few thousand profiles cannot be reviewed before every new role. So nobody does, and recruitment starts over from scratch each time.
Week29 ranks your entire candidate database in Teamtailor by meaning, even when a candidate described the work in other words than the ad, and points to the sentence in the CV when the candidate's own text supports the match.
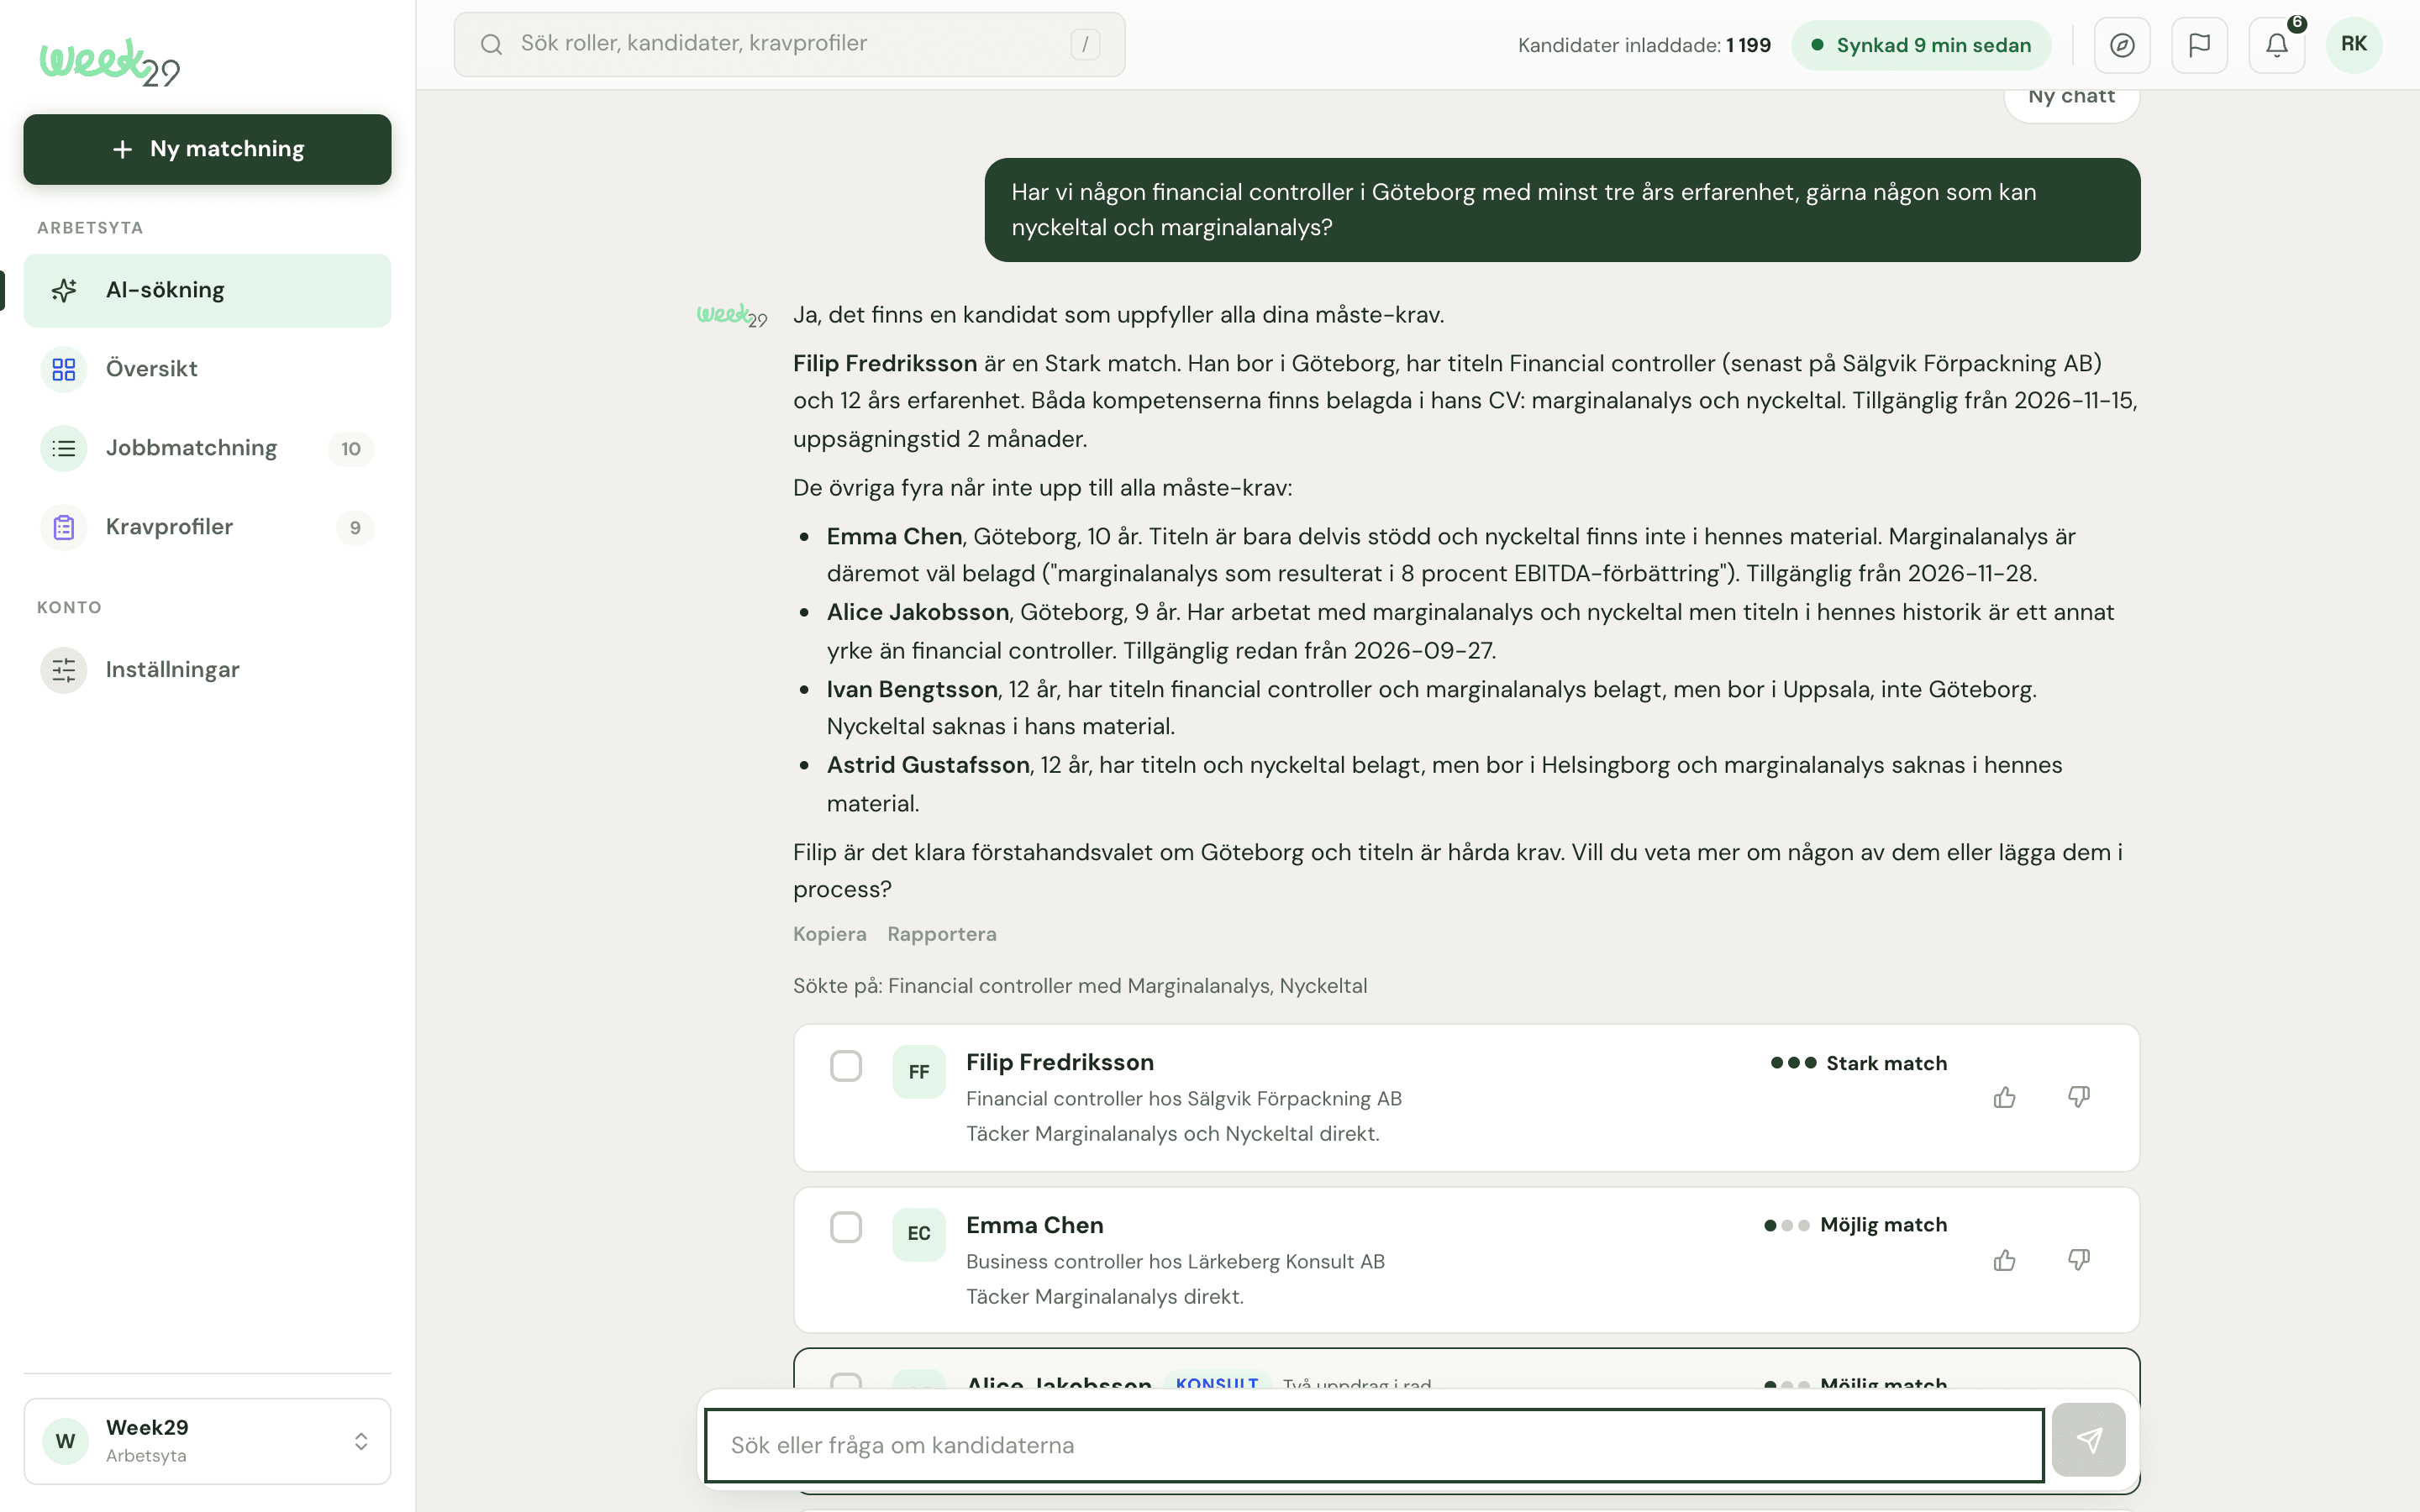
Every ad you have posted left candidates behind. They applied, someone read the application, and the role went to someone else. They are still in the database.
A few thousand profiles cannot be reviewed before every new role. So nobody does, and recruitment starts over from scratch each time.
A candidate may have done exactly the right thing and described it in other words than the ad. A search for exact terms finds the one who happened to use them and misses the one who can do the job.
Most of what says anything about a candidate is in free text, in the CV and the summary, not in structured fields. That is the text we read.
When the candidate's own text supports a requirement, with the word itself or with a phrasing that means the same, we show that sentence verbatim from the material.
Responsible for planned maintenance and operational follow up across the property portfolio, with fault reports and work orders in a digital system.
CMMS Matches CMMS by meaning. The word does not appear in the profile.
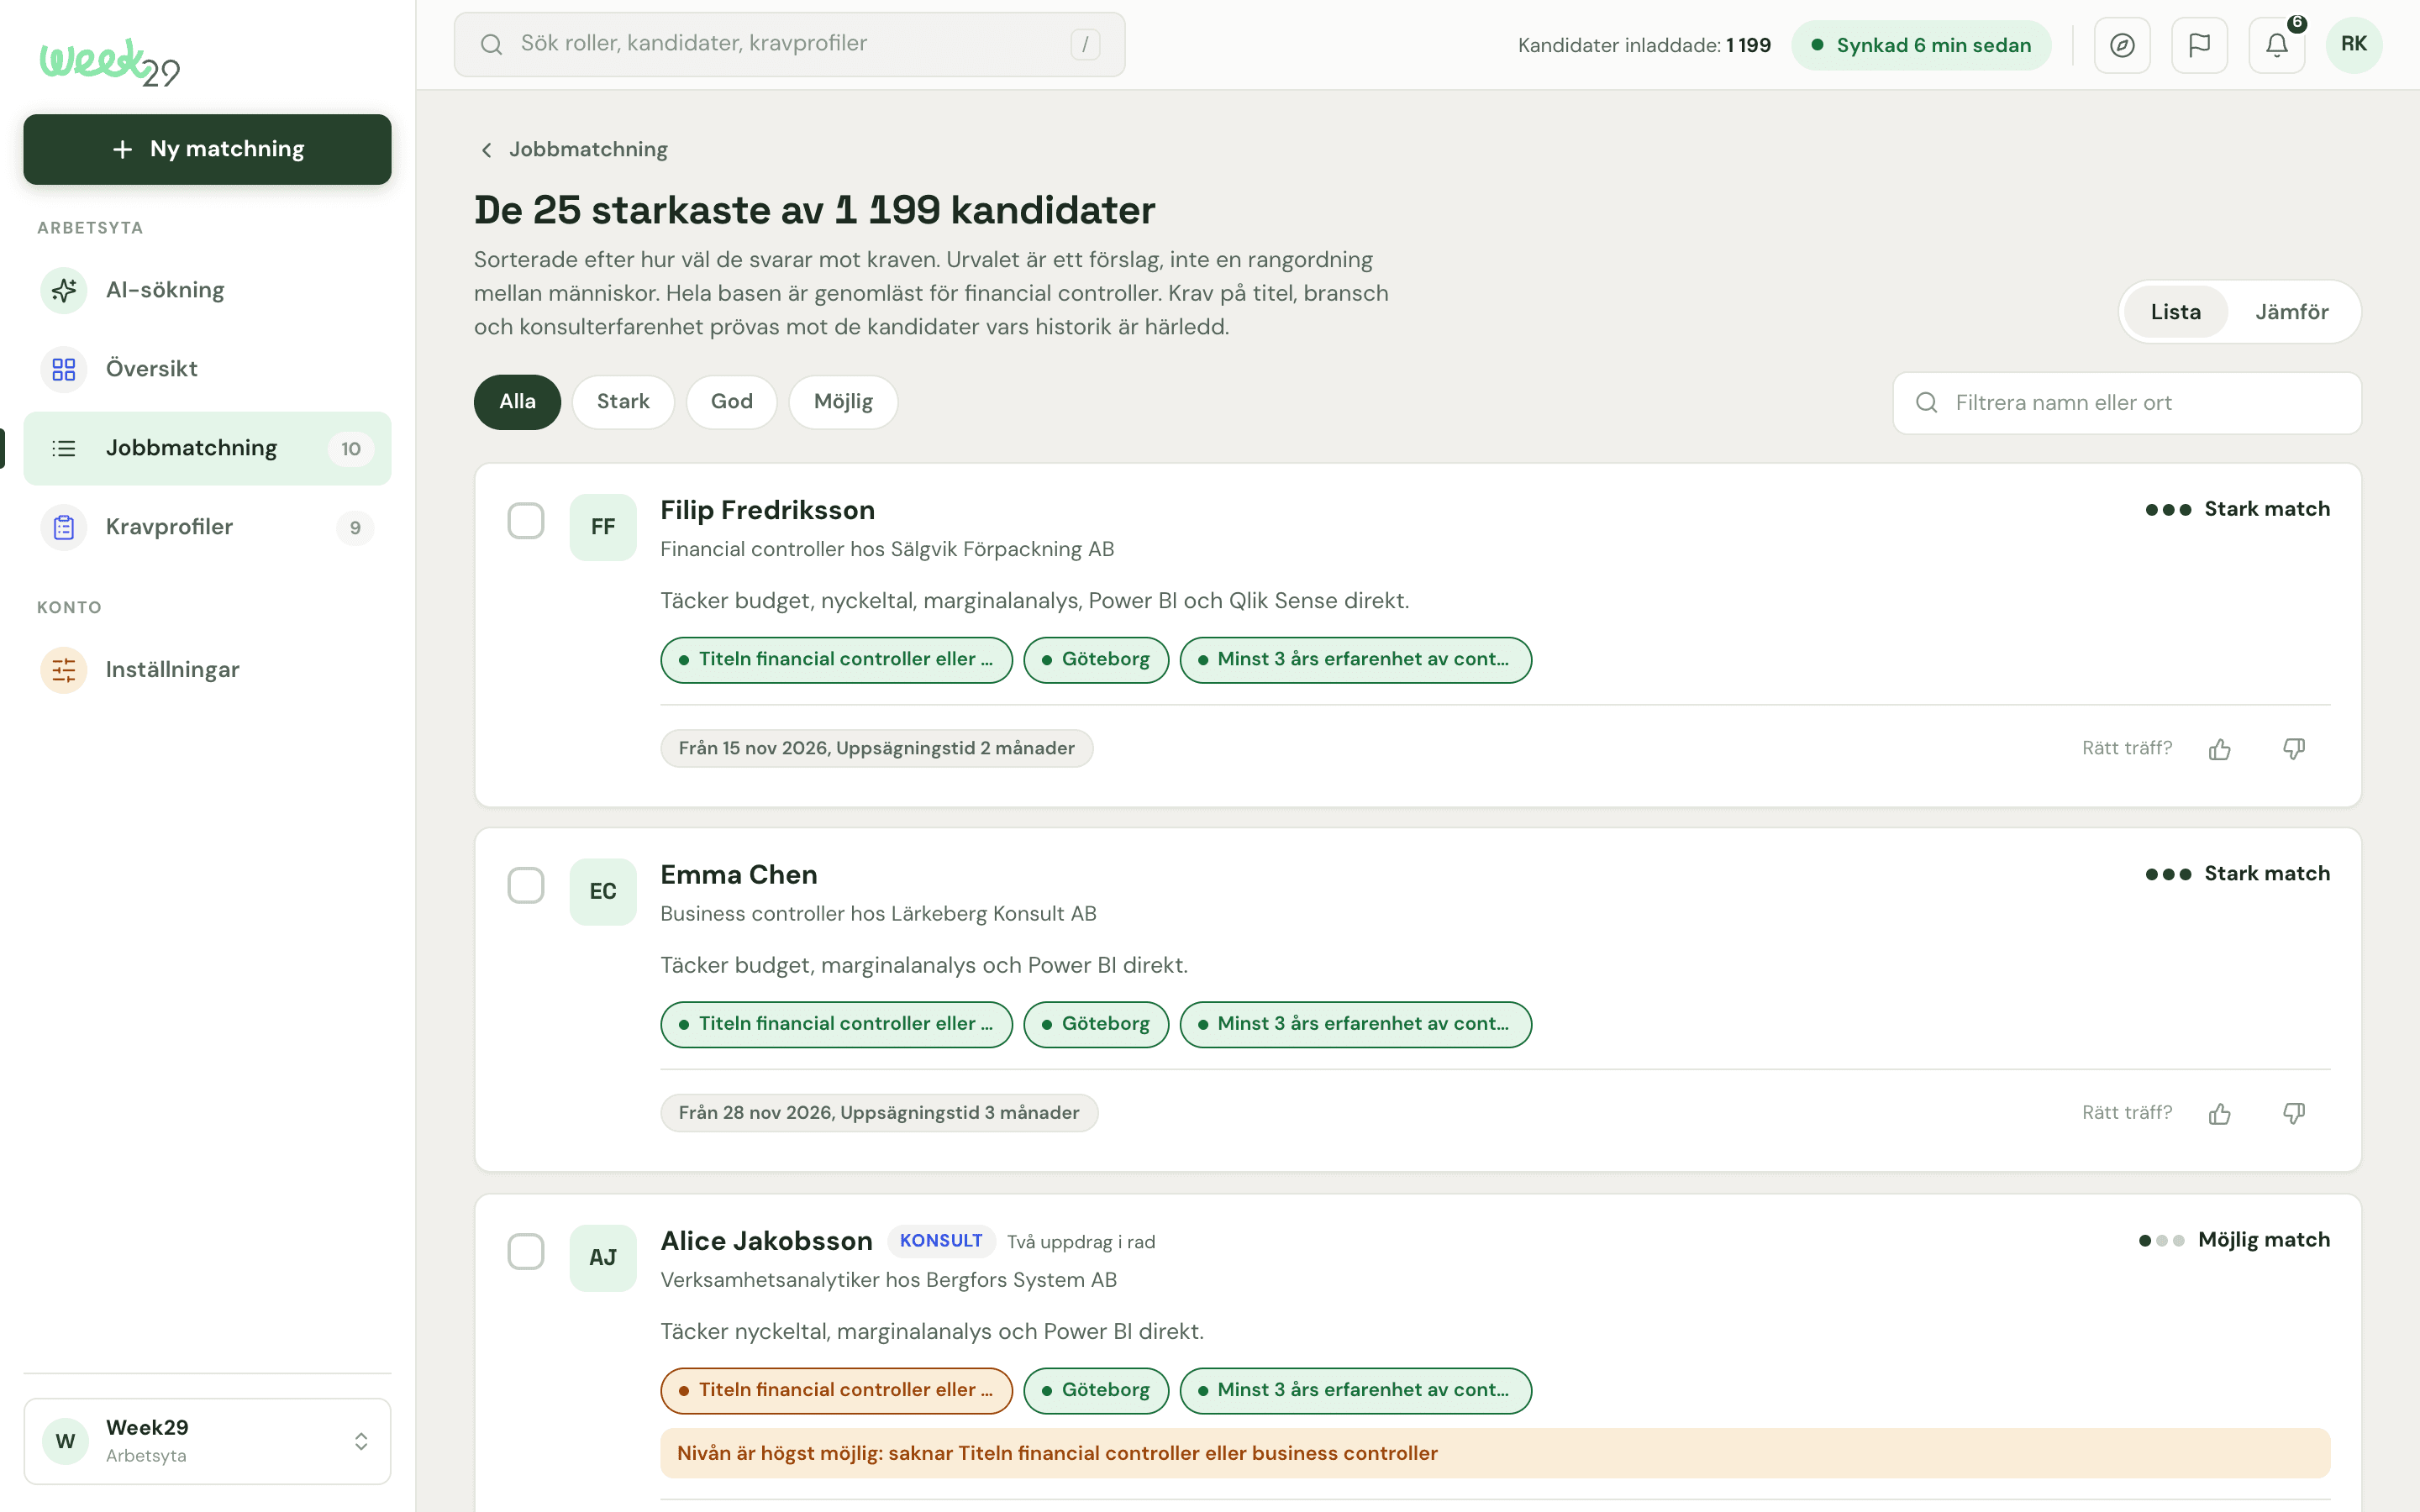
Strong match
Closest to the role, no must requirement unconfirmed.
Good match
Close to the role.
Possible match
Calls for a judgement, or has a must requirement that could not be confirmed.
A percentage looks precise but does not say what is missing, and it tempts you to filter without reading. A level makes the recruiter open the candidate and judge for themselves. So we put no score on a person, in the panel or in Teamtailor.
You do not change systems and you do not change your workflows. Week29 sits on top.
You connect your own key. No migration, no new processes.
Candidates are loaded with CV and free text and made searchable by meaning, in Frankfurt.
The whole database is ranked against the role, with evidence from the candidate's own material.
Through your trigger, the match level is written to the candidate card, where you already work.
The solid steps happen on their own. In the panel, the dashed step requires a person to choose and confirm. If you activate the connection in the Teamtailor marketplace, the match level is written back in the way you set up there.
The ranking, the evidence, the comparison, and an AI search that answers questions about the database. All in one panel, opened from the candidate card.
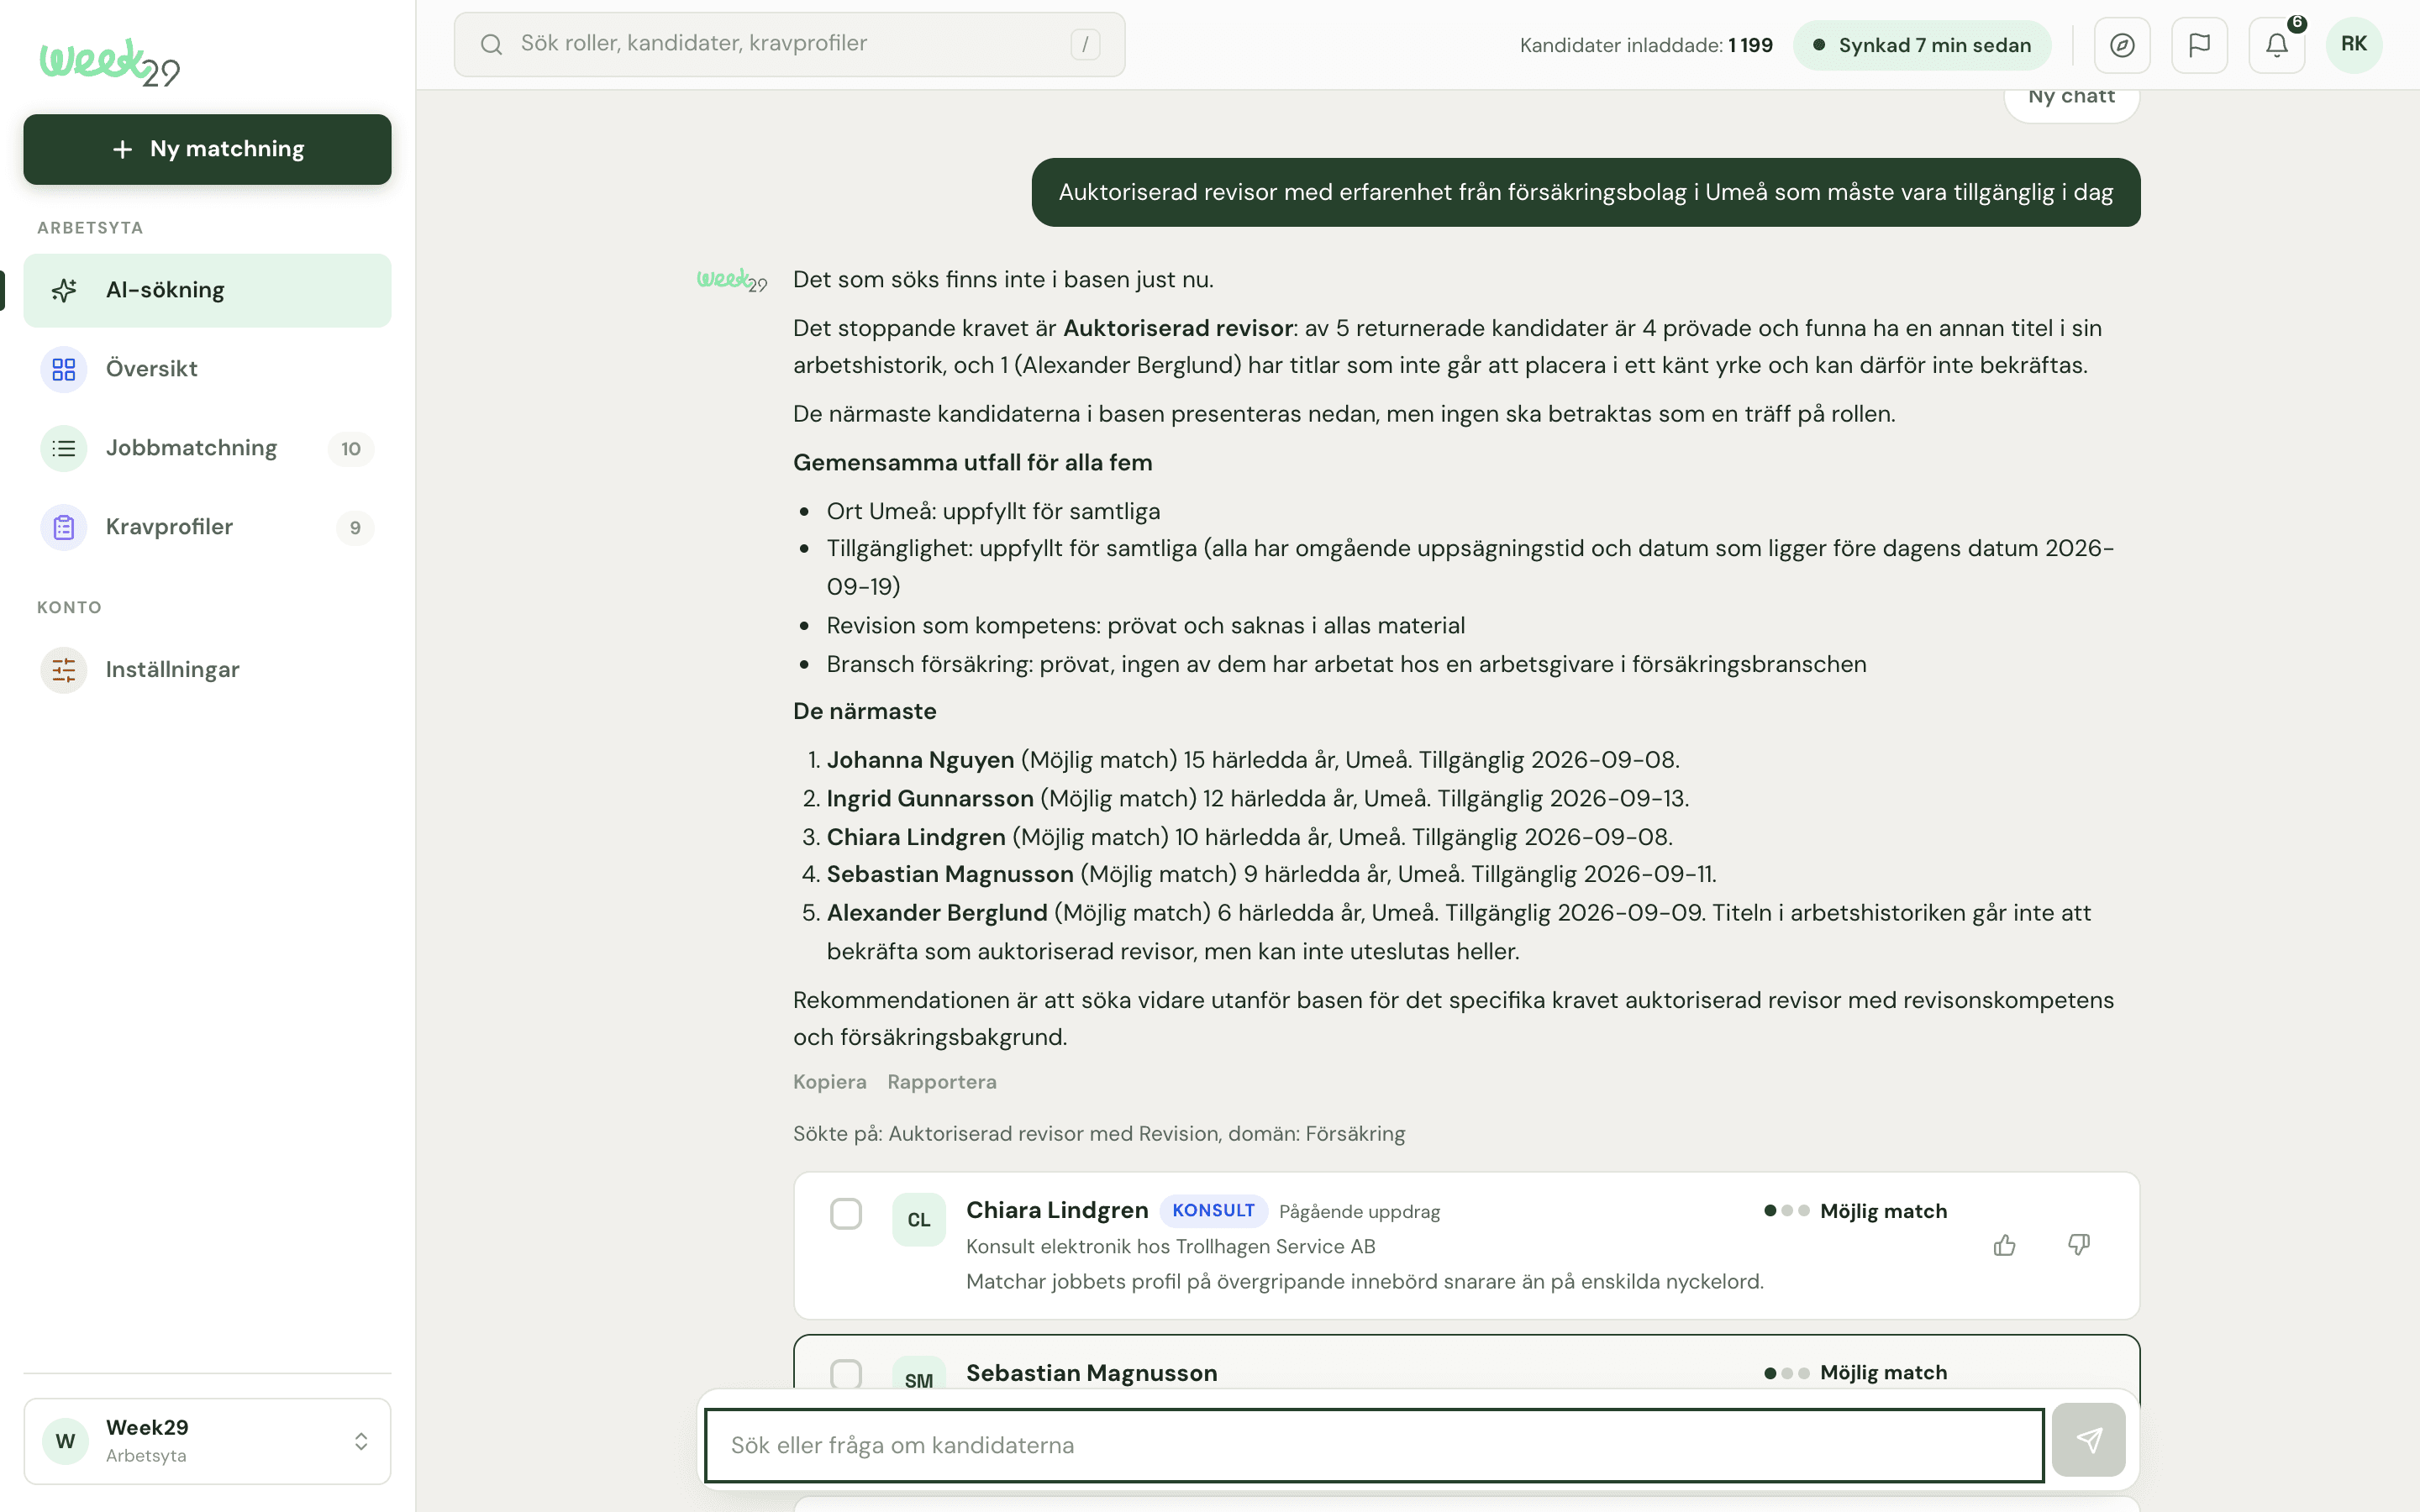
The AI in the panel writes nothing to Teamtailor on its own. Ask it to send candidates and a proposal appears that stays on screen until someone on the team clicks. The block sits in the code, so the model cannot reason its way past it.
read for every role
No search string has to be formulated in advance.
strongest candidates surfaced per role
From the whole database. The list is a proposal to assess, not a decision about anyone.
automated decisions
Decisions about a candidate are always made by a person.
We publish no numbers we cannot show. Speed figures come once they are measured on today's engine.
It is stored in our own database in Frankfurt, inside the EU. You own the data, we are the data processor and use it only to deliver the service to you. We train no models on it, and it is deleted when the engagement ends.
No. Week29 is AI that sits on top of Teamtailor. You keep working in your ATS exactly as you do today, and the result is written back there.
AI that ranks candidates is classed as high risk. We build to the requirements on traceability, explainability and human oversight. Matches with evidence show the sentence in the candidate's text, every processing run is logged, and a person makes the decision. That the AI in the panel cannot write anything by itself is a boundary in the code.
Nobody can promise that. What we promise is that the whole database is read, that evidence is shown when the candidate's text supports the requirement, and that a person decides. You read the evidence and form your own judgement.
We do not publish prices yet. Book a demo and we will go through what Week29 costs for your database and your team.
You connect your Teamtailor key in the app, then we load the database. No migration and no new processes. How long the load takes depends on the size of the database and how much CV text it holds.
Week29 is built as a Teamtailor integration. If you run another ATS we would like to hear about it, but Teamtailor is what we support today.
We show the ranking, the evidence and the controls, and answer the questions about data and regulation. It takes thirty minutes.